Attention, trained end to end
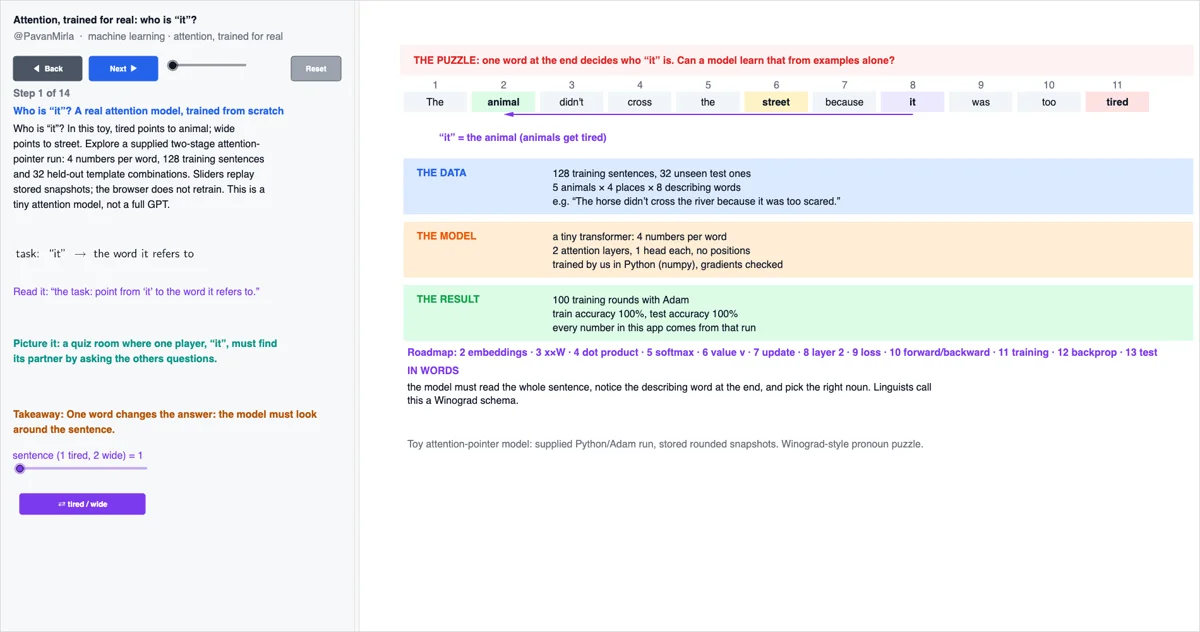
Follow a tiny trained attention pointer through embeddings, Q/K/V, residuals, a second attention stage, cross-entropy, backpropagation and Adam updates.
Fourteen interactive steps with Coach–Zon dialogue connect a prediction to the gradients and optimizer updates behind learning. This separate deep dive complements the original multi-head attention overview.
Explore next
Stories, illustrations, and interactive mini lessons. Ask a question.