Learning from a teacher: soft multi-token prediction
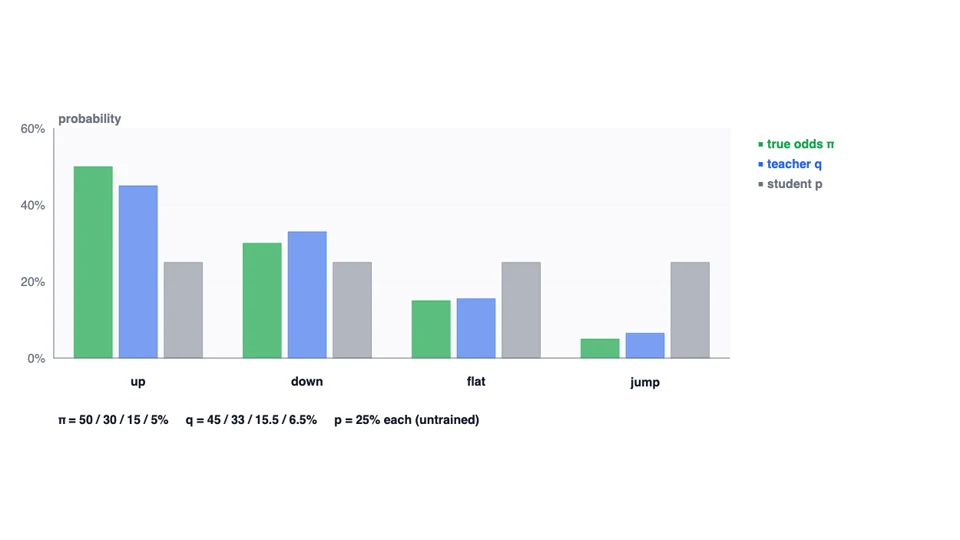
ML015 uses an original up/down/flat/jump toy world to separate a teacher-matching gradient, teacher error and sampling noise.
Compare hard and soft gradient errors, explore stop-gradient routing, and see why matching a teacher improves draft acceptance.
Inspired by recent research: Jayden Teoh, Multi-Token Prediction Done Right (2026), arXiv:2610.38331v1. This lesson uses original wording, examples and numbers.
Explore next
Stories, illustrations, and interactive mini lessons. Ask a question.